
Understanding Open Knowledge Format Value Proposition
Foundation models keep being released at a neck-breaking cadence. Each release improves, even if marginally, on the previous version’s benchmark results.
The result: stronger models with capabilities for longer and longer sessions. Yet, they are still oblivious to your context.
Through their increased tool support and system prompts, they can partially address this by searching your repositories and discovering (or inventing) patterns.
While that works up to a point, it is inefficient and is fairly uneven between harnesses & models.
Alternatives, under the so-called context engineering, include creating AGENTS.md (or equivalent files) and pointing your harnesses to use them as part of the tasks. This is not an easy task, as the content can be spread across multiple sources.
Google introduced Open Knowledge Format (OKF) as an open specification to formalize the LLM-wiki approach, creating a vendor-neutral and human-friendly standard for this context feeding/generation problem.
At the heart of it sits the concept of a bundle, which is a self-contained collection of knowledge documents organized in a hierarchical way.
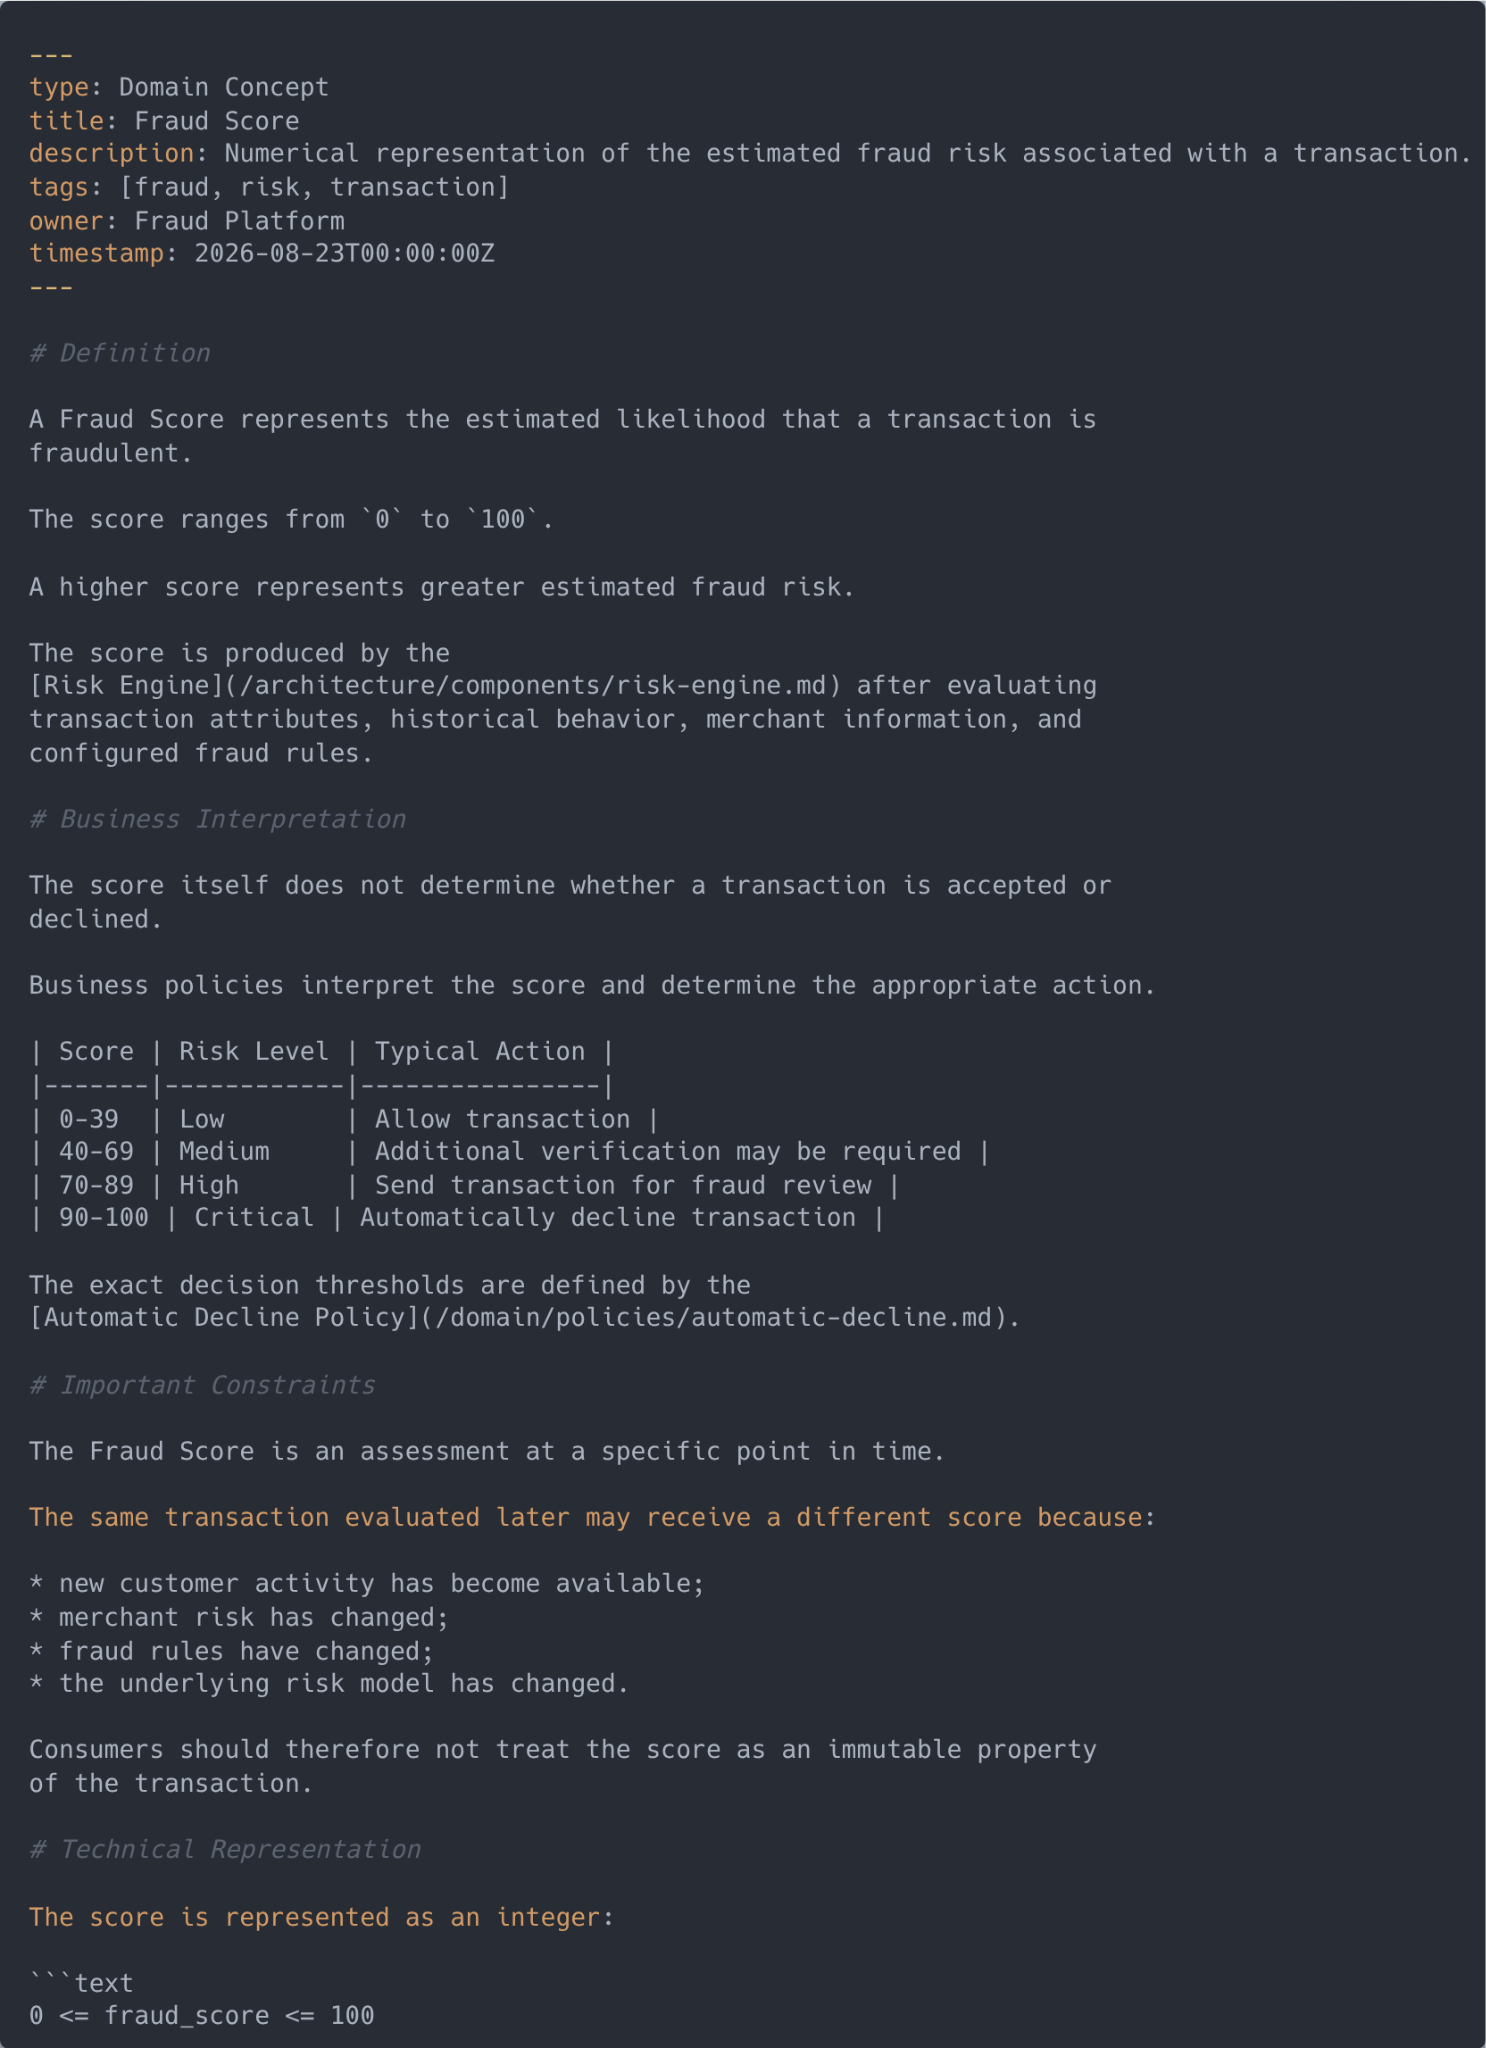
Like agent skills, each unit of knowledge (concept) in the bundle is a .md file containing YAML frontmatter with standard fields and a body containing regular Markdown.
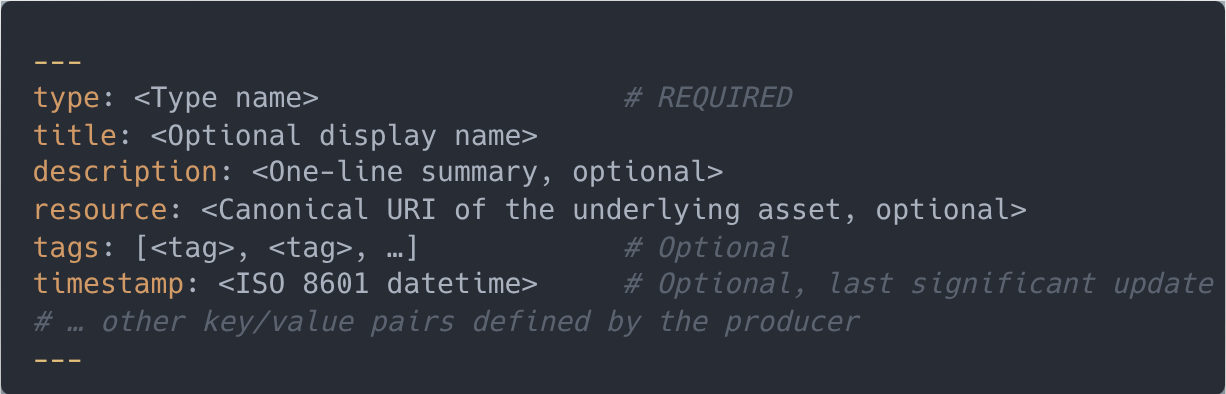
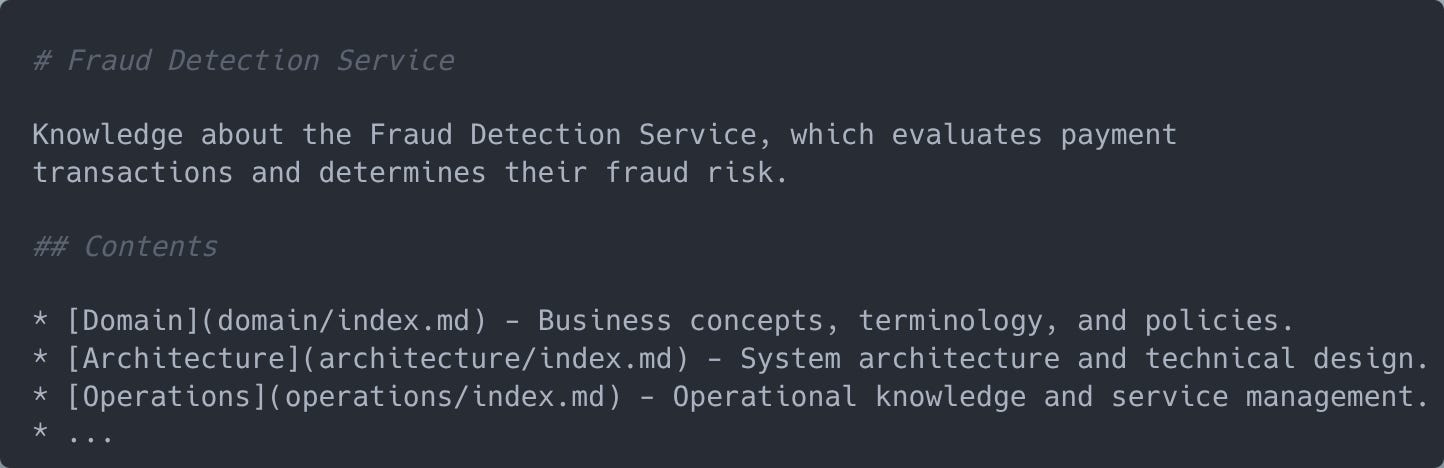
To benefit from progressive disclosure, list each concept in an index.md file per subfolder.
Imagine one of your services would have this bundle
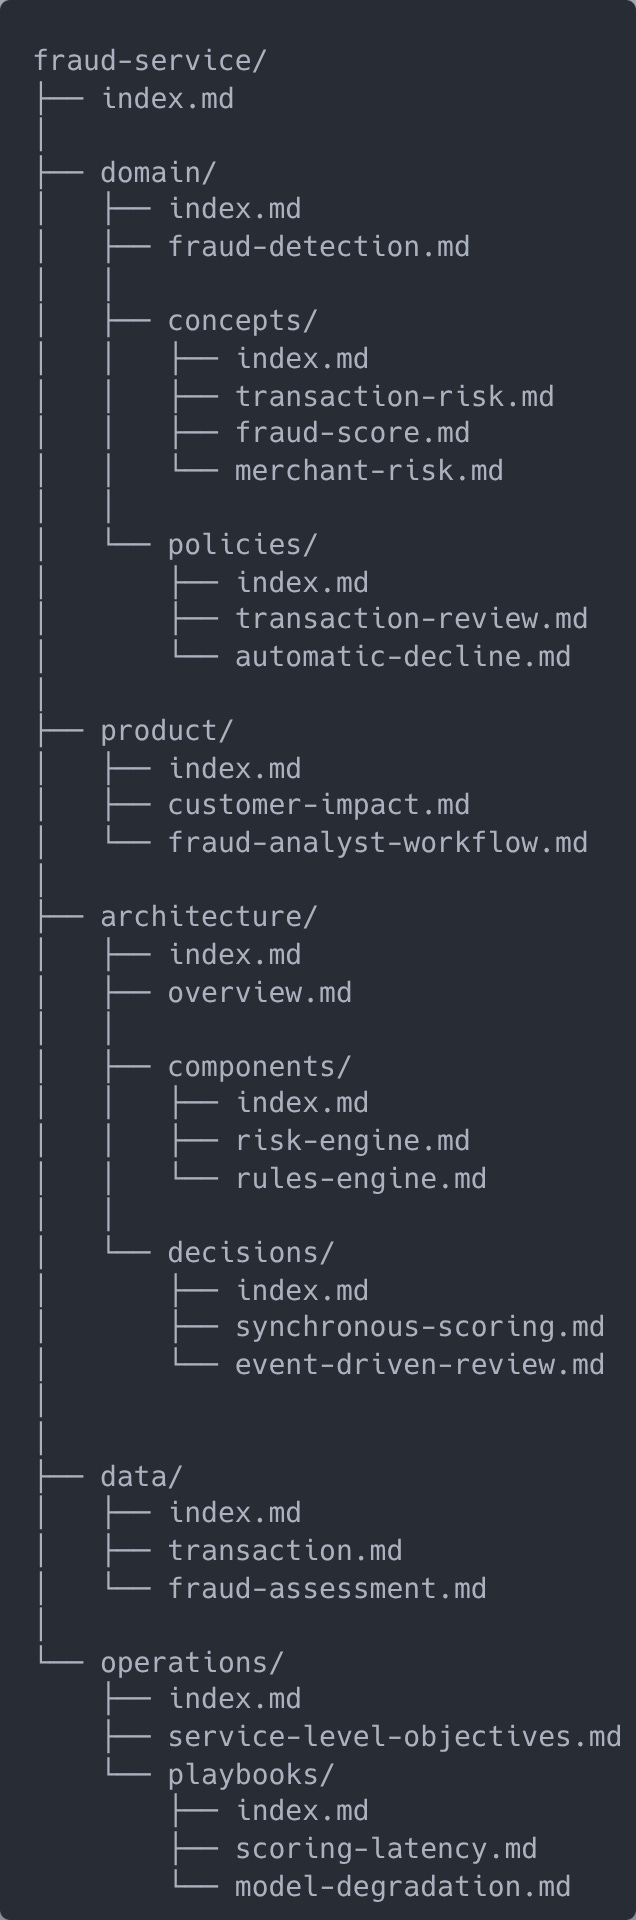
Starting from the top, we have an index.md that lists the contents of the level it is located in.
Each concept gets its own file, such as this fictitious domain/fraud-score.md
If you follow this approach, you have a curated set of knowledge that is packaged in each bundle.
This bundle can be fed to the agent as part of future work with some gains:
By having the index.md you provide progressive disclosure. The agent does not need to scan your repository to find (or infer) the concepts it needs
By being accessible to the agent, it can be maintained with its help. As you make changes to the repository (example, developing a feature), the agent can update the relevant bundles
It is human-readable, which helps with both maintenance and support
It is vendor-neutral, bringing the versatility to adopt independent of the harness and model used
But before jumping in, let’s not forget that this is a relatively new format, with version 0.2 being released in July 2026. It also does not solve the issue when you have concepts that sit in other media or applications.
At best, you can create a .md file for that concept and add a link to that external application, but maintaining the links or accessing the actual content is beyond OKF’s goals.
LangChain vs LangGraph: 4 Key Differences and When to Use Each
Every single company, independent of its size, seems to be united behind the concept that AI agents are the future and they will unlock productivity gains.
While there is much debate about the actual impact of those agents, one thing is certain to me: almost no one knows what an AI agent is, and for those who do, how to build and maintain one is equally unclear.
For example, LangChain and LangGraph are often mentioned during conversations in an interchangeable fashion, while there are differences between what can be accomplished by each one. This article does a good job of comparing both, so we know when to use one or the other.
Pipelines vs Loops
LangChain provides you with the primitives to create pipelines, which can be seen as directed acyclic graphs (DAGs). A fancy name for a linear, one-way flow of execution.
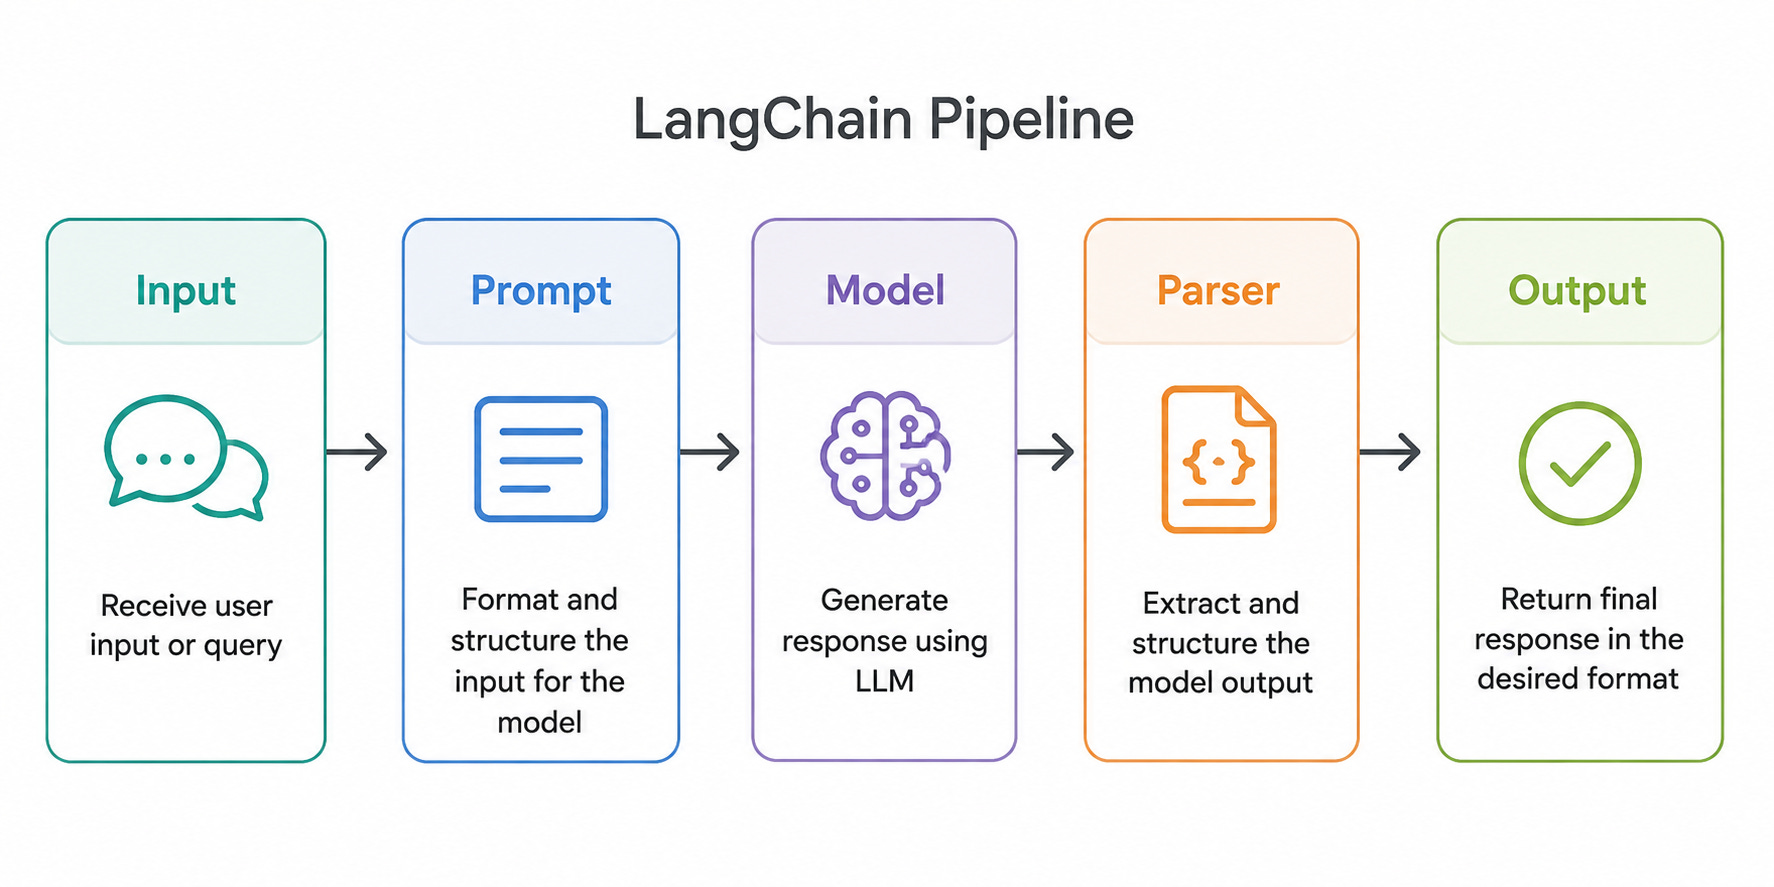
Because of the unidirectional nature, if we need to provide some sort of feedback, where one output would be used for a new interaction, LangChain does not help us, and we need to resort to regular language constructs (aka outer Python loops), which means this aspect is not managed by LangChain itself.
LangGraph offers loops as part of the workflow itself, so as part of conditional branching, you can decide to route back to earlier nodes.
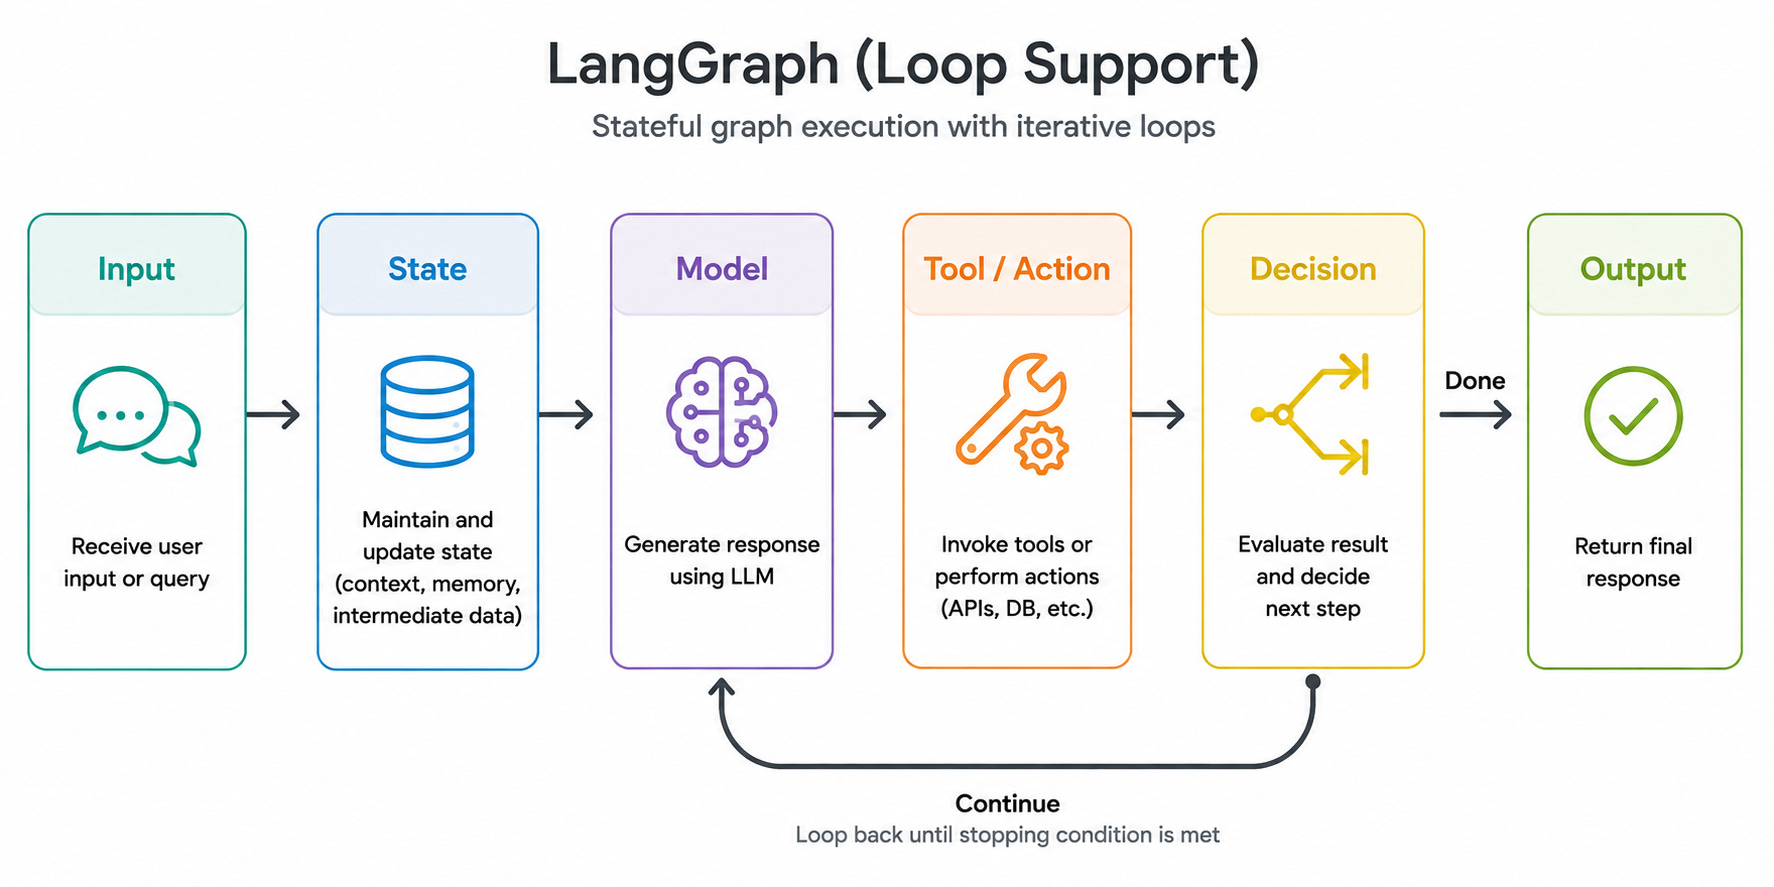
Stateless vs Stateful
A standard LangChain runnable pipeline is stateless, with each node’s output being passed forward (dictionary, message, custom object).
This is normally ok for DAGs, but once loops are involved, LangGraph can provide native capabilities by making the AgentState a first-class concept.
Each node does not need to pass forward the entire state; instead, it outputs just what it needs to, and LangChain updates the state accordingly. So imagine we have the following definition:
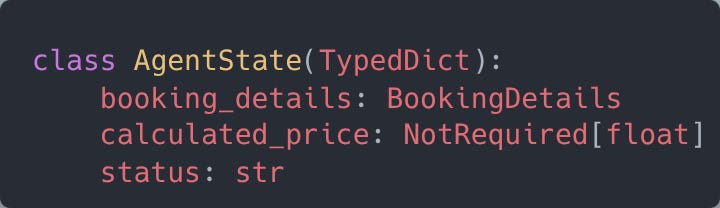
Then a node is invoked to calculate the price:
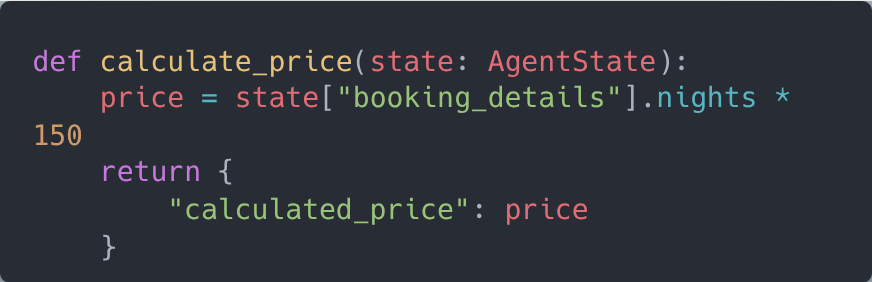
The before and after of the state would look like this
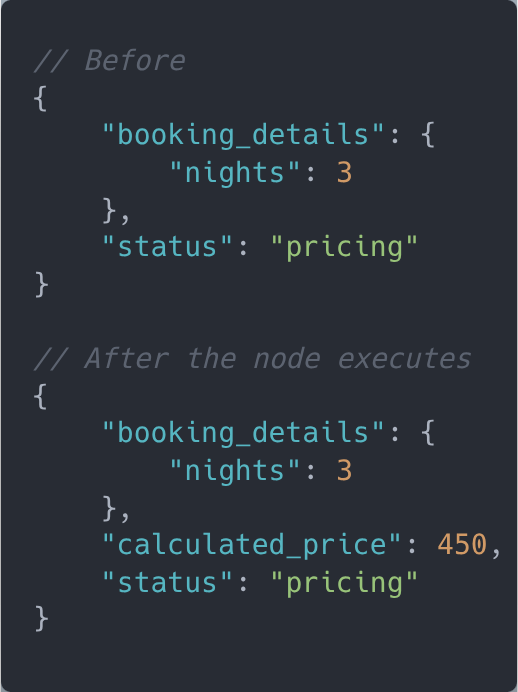
Much simpler than before.
Human-breaks-the-loop vs Human-in-the-loop
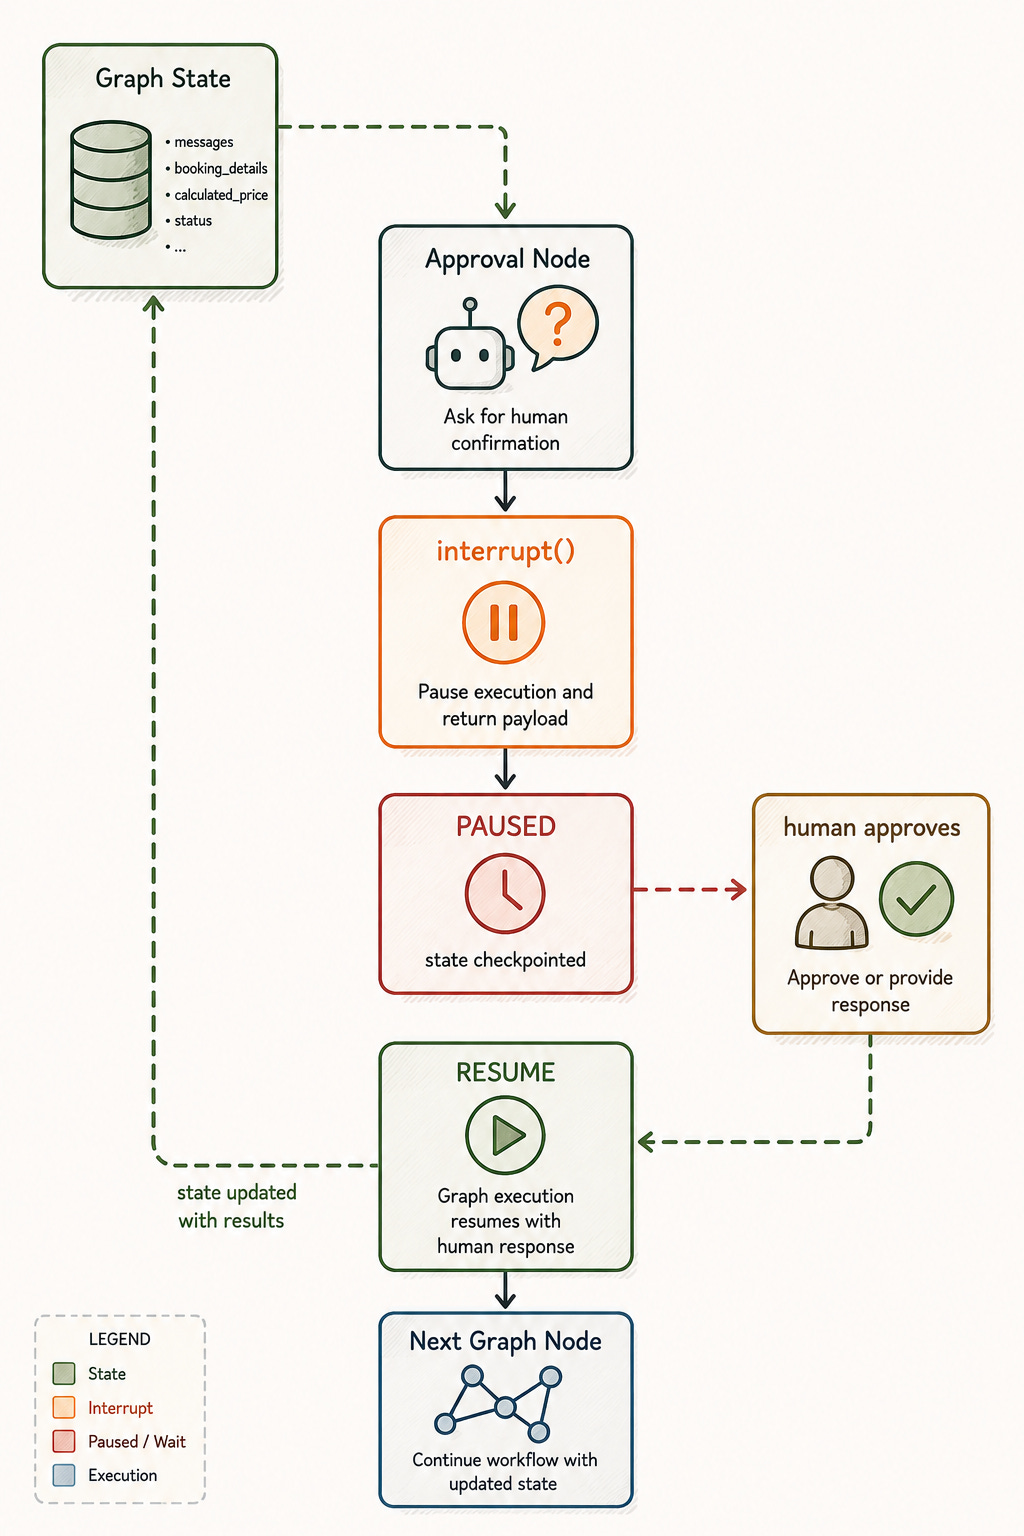
Because of the sensitive nature of the tasks that can be carried by the agents, you may want to have some sort of approval, where the agent goes on until a decision is necessary and waits until an answer is provided.
With LangChain, you can implement this by essentially breaking your pipeline into two:
One that reaches the point until an action is proposed.
You save the proposal, notify someone/some other system, and wait for approval.
One that executes the action
You reconstruct the context based on the saved proposal and start the execution of this second pipeline
LangGraph adds support for an interrupt primitive that handles most of that on its own. So the application interacting with LangGraph still needs to route the approval request back and forth, but LangGraph will resume and pass the response to the node.
Restarts vs Resume
When a step in a LangChain fails, attempting to invoke the chain again is tempting but can be costly and, if the steps are not idempotent, lead to issues. You can avoid at the application level by adding some sort of cache to effectively avoid reexecuting the steps that succeeded, but it is cumbersome.
Since LangGraph supports checkpoints (see the previous example), this execution-after-failure is available for us.
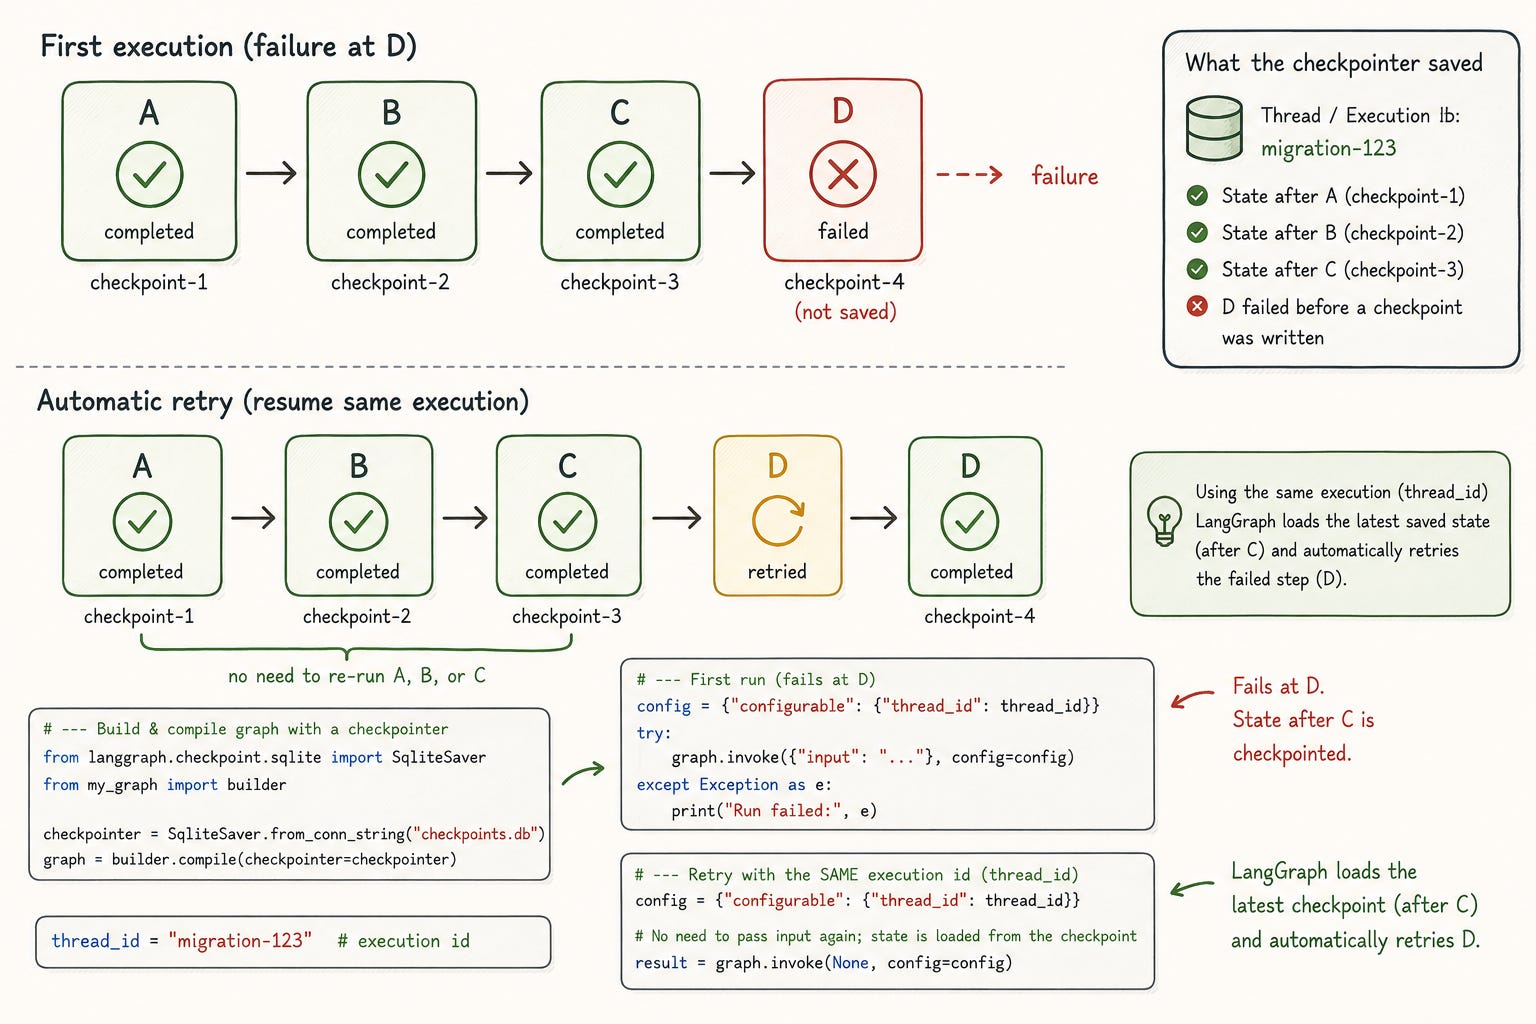
While both solutions can work, understanding their limitations or uses helps to choose based on what you need to support.
How to Manage Connections Efficiently in Postgres, or Any Database
At the heart of most applications, there is some sort of persistence, saving the state of the system as your users interact with it. Relational databases, like Postgres, have been used for this purpose for decades.
Before the advent of the commercial Internet, usage was more contained, as the audiences of those systems were more or less predictable, especially as ceiling traffic goes. All of a sudden, connected, 24/7 systems became the norm, leading to cases where your application and its persistence can expect sudden increases in demand.
A common problem found in these cases is the inability to reach your Postgres server due to a lack of available connections.
This article covers the usual problems and proposes 3 solutions you can use to handle the problem.
Use connection pools
The lifecycle of many applications consists of establishing a connection to the database, executing the queries, and closing the connection at the end.
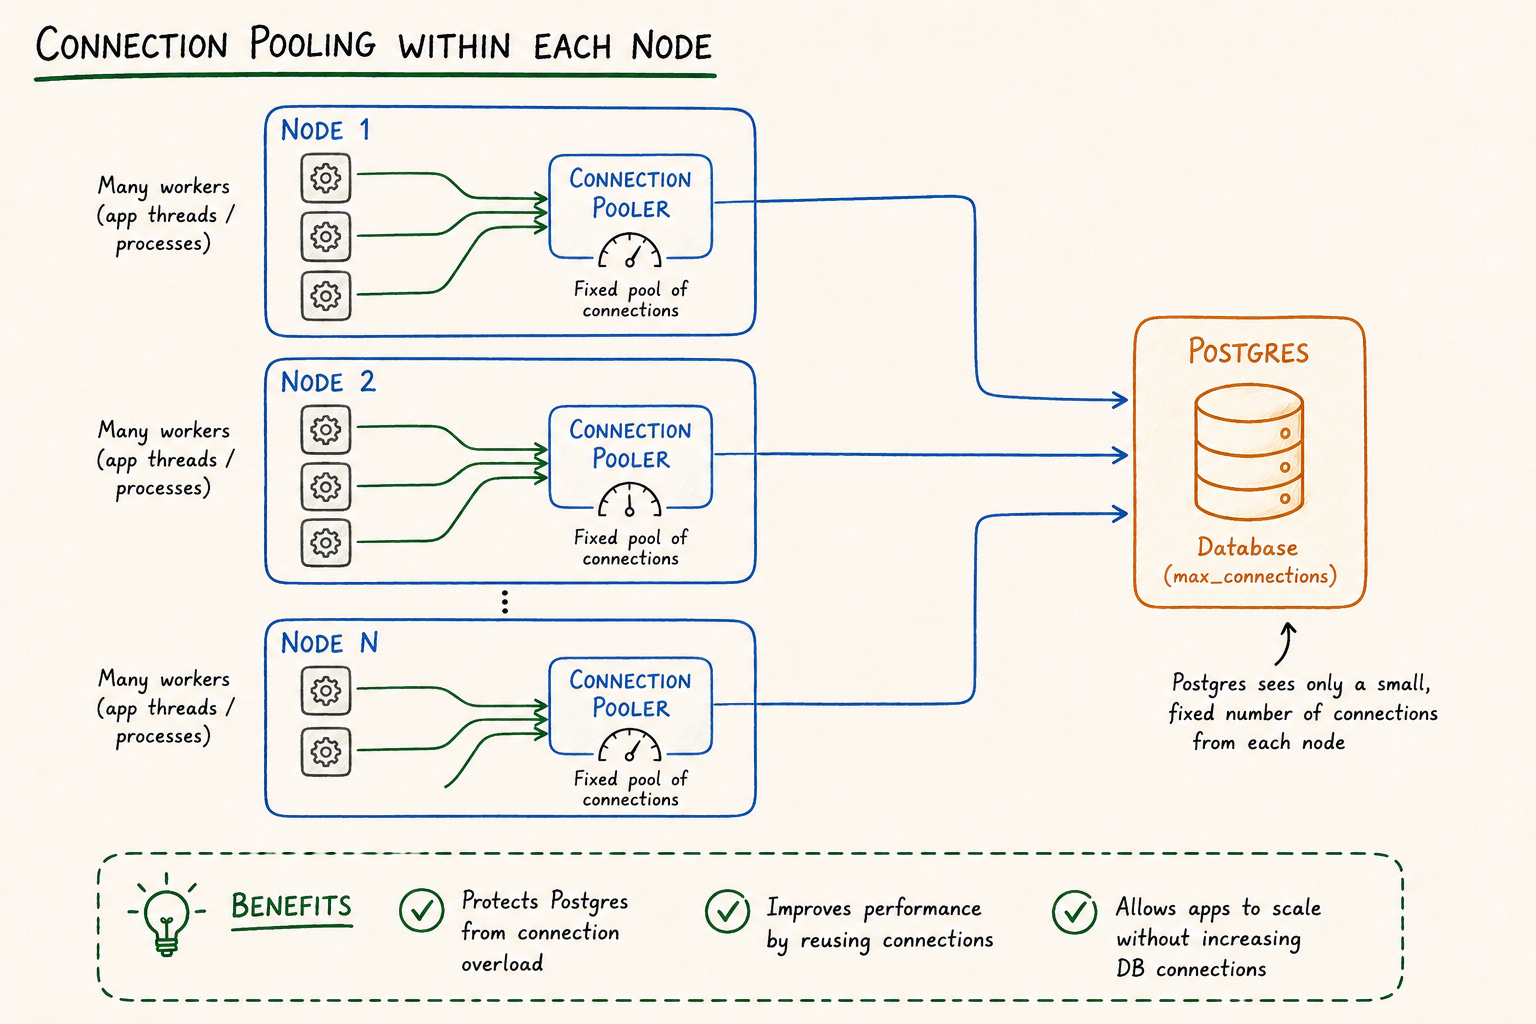
A connection pool is configured within each node, and it has a maximum number of connections. The workers within the node share those connections by requesting them from the pool, instead of directly talking to the server.
This provides a more deterministic number of connections to the server and can reduce the cost (time) to execute your operation, as the connection is already available.
Minimum viable checkouts
The idea draws parallels from critical sections found in concurrent programming, where we want to minimize how long the resource is needed, effectively making it available for other processes.
Think of your application; it may execute initial work related to the deserialization of bytes received, schema validation (pre-work), then the actual DB is needed to persist the information, followed by another part of the code where you are transforming the information to be sent back.
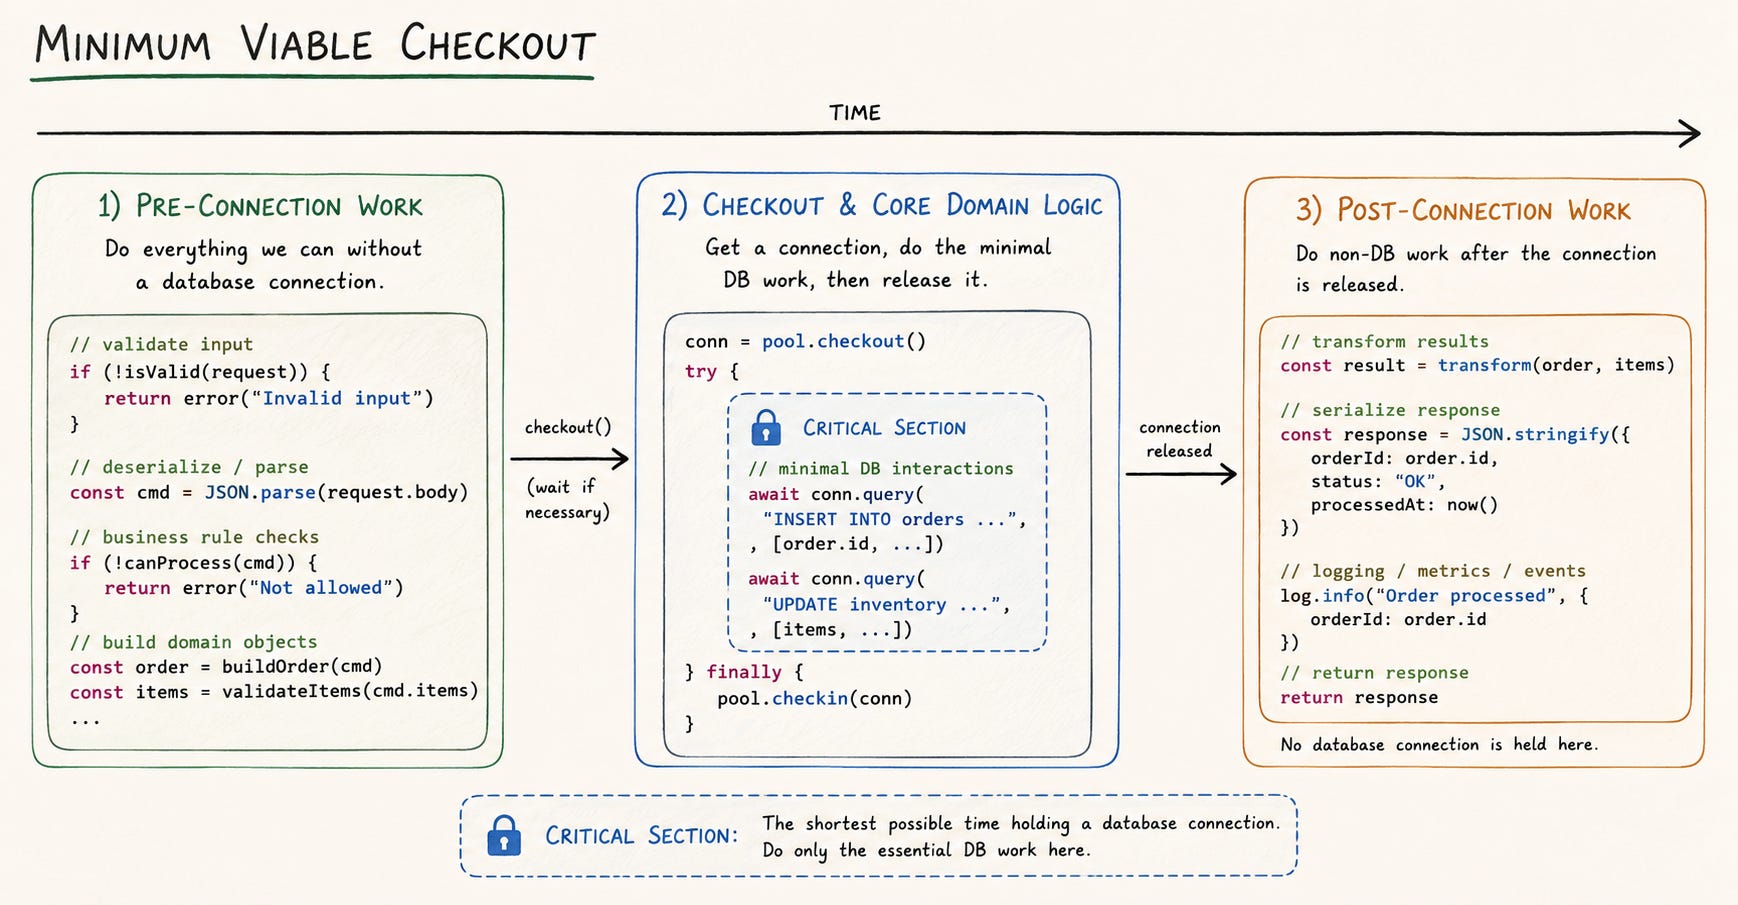
Depending on the scale and what happens (pre/post connection), this can help you make the most of the available resources.
Inter-node pooling
This is a more advanced version of pooling that takes place outside the working nodes to enable a more precise tuning of the connections among different nodes.
The benefit of this comes when you end up with some sort of imbalance between the nodes. Having this outside pooler can control the limit of connections by having access to all connections across nodes.
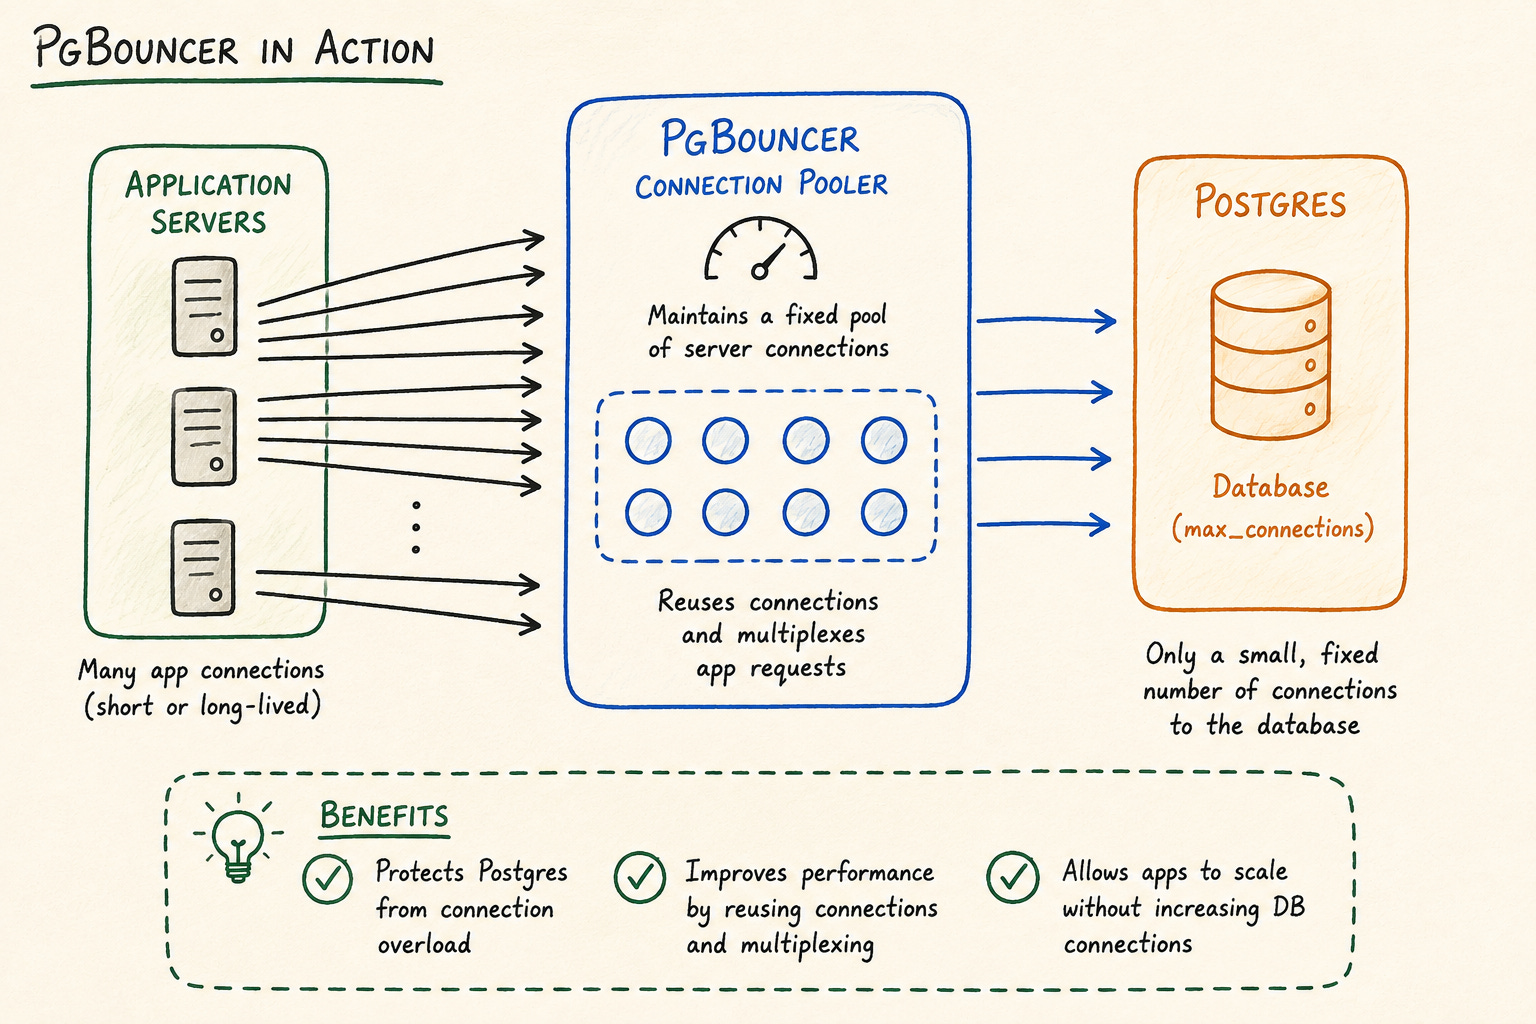
The key takeaway is that connections have to be considered as a resource like many others you have.
This can take a while to sink in, as during development or regular operations everything works fine.
Looking for more information about software architecture, development, and AI? Check my blog here or visit architecturecorner.dev for information on courses.